Querying traces
While the span query language operates on individual spans and logs, trace queries allow you to select entire traces based on the spans, logs, and events they contain. This is useful for finding traces that match complex criteria across multiple services and operations.
For example, you can find all traces that contain a slow database query, have an error in a specific service, or involve a particular combination of microservices.
Query Structure
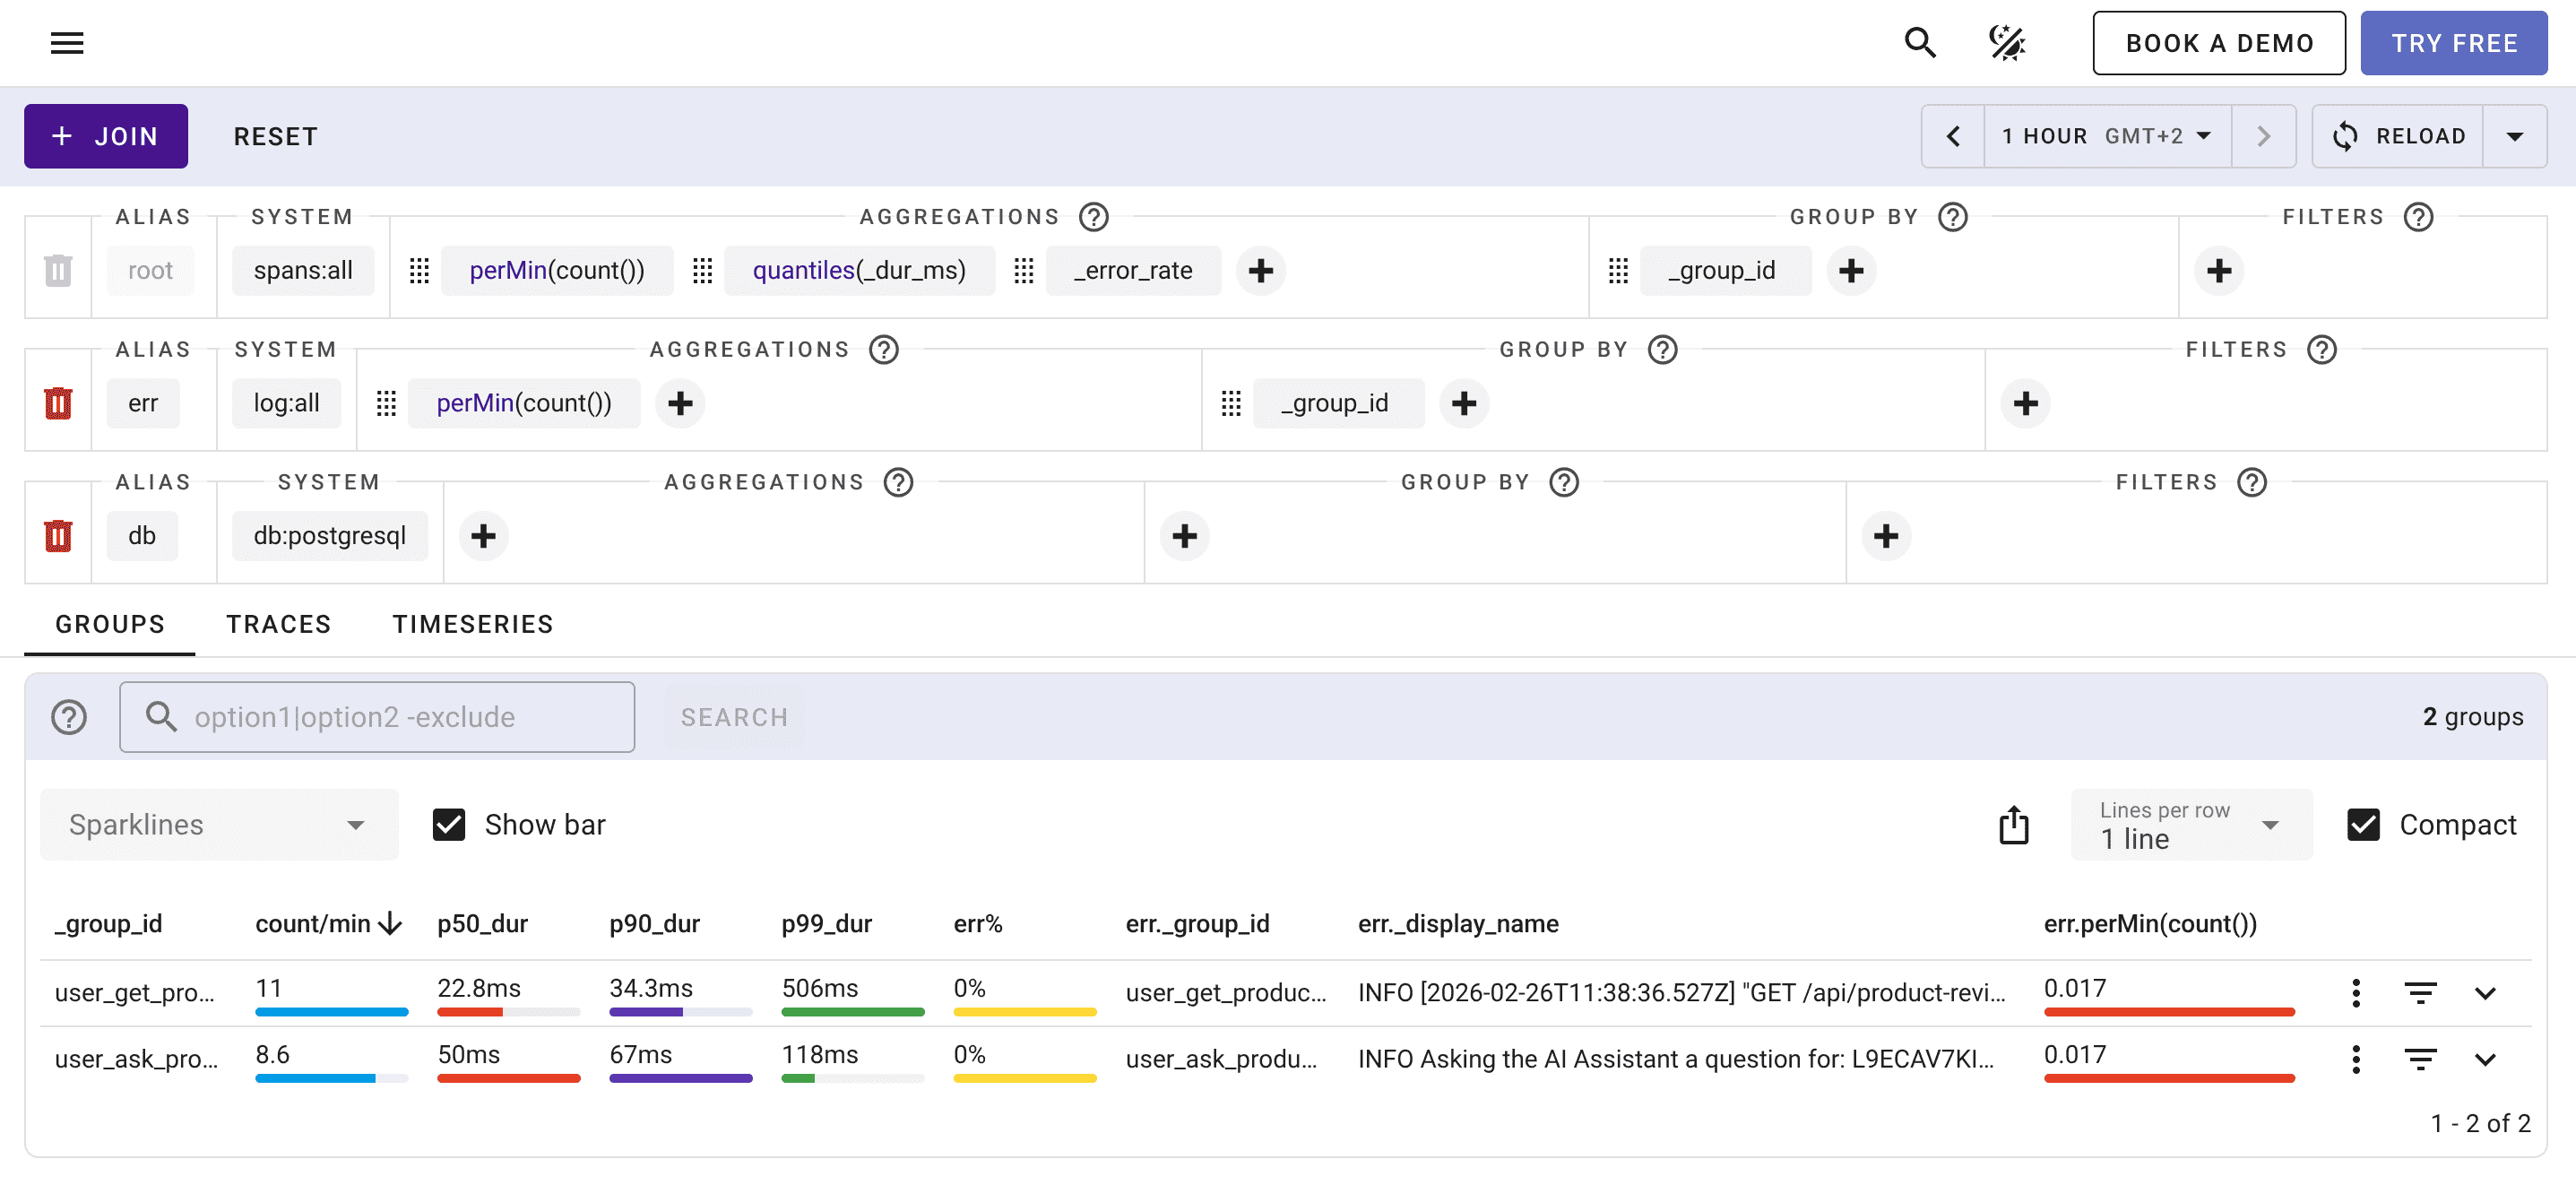
A trace query consists of multiple rows, where each row targets a different part of the trace. The first row is always the root row, and subsequent rows define conditions on child spans, logs, or events.
root: <query for the root span>
<system> as <alias>: <query for matching spans>
Each row accepts the full span query language including filters, aggregations, and groupings. A typical root row query looks like:
root: perMin(count()) | quantiles(_dur_ms) | group by _group_id
| Component | Description |
|---|---|
root | Selects the root span of the trace. Use <empty> to match all root spans. |
<system> | A span system like db:postgresql, rpc:all, or log:error. |
as <alias> | Names the row. Optional for readability, but required to reference the row from the root with a cross-join expression ($alias.attr). The alias must be unique and cannot be root. |
<query> | Full query with where, group by, and aggregate clauses. |
The root row is scoped to root spans with where _parent_id = 0, and each child row excludes them with where _parent_id != 0. These are ordinary clauses, visible and editable in the query bar, and a cross-join relies on them — a query whose root row references no _parent_id at all is rejected rather than silently over-counting. On a log or event row the same clause keeps records that are attached to a span.
Filtering by System
Each non-root row targets spans belonging to a specific system. You can use exact systems or wildcard systems with :all:
| System | Matches |
|---|---|
db:postgresql | PostgreSQL database spans only |
db:mysql | MySQL database spans only |
db:all | All database spans (PostgreSQL, MySQL, etc) |
rpc:grpc | gRPC spans only |
rpc:all | All RPC spans |
http:service1 | HTTP spans for service1 |
httpserver:all | All HTTP server spans |
messaging:kafka | Kafka messaging spans only |
messaging:all | All messaging spans |
log:error | Error-level logs |
log:warn | Warning-level logs |
Cross-Join Expressions
The rows shown so far each match spans independently — a trace is returned when every row finds at least one matching span. To bring a child row's values into the result, you have two options.
Aggregate in the child row. The simplest way to expose a child value is to compute it in the child row itself; its selectors become $alias.col columns on the root:
root: count() | group by _group_id
db:all as db: max(_dur_ms) as slowest_query_ms
Reference a child from the root with $alias.attr. A cross-join expression lets the root row aggregate a child's attributes inline, where alias is the as <alias> name of a non-root row:
root: count() | merge(p90($db._dur_ms)) as db_p90_ms | group by _group_id
db:all as db:
Both positions mean exactly the same thing — max($db._dur_ms) in the root equals the child row's own max(_dur_ms), and both follow the grain rule described below. Prefer the child row whenever you just need a child value as its own column. What the root form adds is that it can combine a child aggregate with a root aggregate in one expression — a trace's own duration, for instance — which a child row cannot do, since it only sees its own spans:
root: count() | max(max($db._time) - min(_time)) as slowest_trace_ms | group by _group_id
db:all as db:
The join is always on trace id, so each $alias.attr only sees spans in the same trace as the root span. A single aggregate stays within one alias, and so does a compound expression: an expression that combines a child aggregate with arithmetic may reference only one join alias. To read values from two child rows, give each its own selector and compare the resulting columns.
How a Child Row Is Evaluated
A child row is evaluated as a subquery grouped by trace id, so every selector is first computed per trace — count() is the matching-span count in one trace, max(_dur_ms) the slowest span in one trace.
The result table is then grouped by the root's group by, and one result cell can span many traces. This is where the language's central rule applies:
A bare aggregate is a per-trace value. When a cell holds several traces, it is exposed as one representative trace's value — an implicit any(). Cross-trace re-aggregation is never implicit: it is always spelled out, either as a specific merge wrapper (sum(count())) or as the aggregate's own natural merge (merge(count())).
So db:all as db: max(_dur_ms) is the slowest query in one of the cell's traces, not the slowest in the cell. For the latter, write merge(max(_dur_ms)) or max(max(_dur_ms)). The rule is the same in every position: a child row's own selector, a root $alias.attr reference, and a member of a per-trace expression.
A cross-join assumes one root span per trace — the default root row matches root spans only (where _parent_id = 0), and each child row excludes them (where _parent_id != 0). If a trace has several root spans (a malformed or duplicated trace), its child values are joined to each root span, so additive merges (sum, count, avg, percentiles) over-count; idempotent ones (min, max, any, uniq) are unaffected. A per-trace expression collapses such a trace to one root span's value.
Reference Forms
Four forms decide what a reference means across a cell's traces. They compose: a rate function may wrap any of the other three.
| Form | Across the cell's traces |
|---|---|
count(), max($db._dur_ms) | One representative trace's value — an implicit any(). any(count()) spells it out. |
f(agg()) where f is any, min, max, sum, avg, count | A specific plain merge of the per-trace values. |
merge(agg()) | The aggregate's own cross-trace strategy. |
perMin(E), perSec(E), rate(E) | Transparent to grain: scales whatever E means by the time window. |
The merge wrapper reads naturally once you know the inner value is per-trace:
| Wrapper | Across the cell's traces |
|---|---|
sum(count()) | total matching spans |
max(count()), min(count()) | the most / fewest in any one trace |
avg(count()) | mean per trace |
count(count()) | number of traces in the cell |
any(count()) | one representative trace's count |
merge() is the only form that can express a merge no plain re-aggregation of finalized values can reconstruct:
merge(count())— the cell total, same assum(count()).merge(p90(_dur_ms))— the pooled percentile over all the cell's child spans.avg(p90(_dur_ms))is a different number: the mean of per-trace p90s.merge(uniq(service_name))— the deduplicated distinct count across traces. A plain merge would count a service once per trace.merge(avg(_dur_ms))— the exact ratio, computed from the summed numerator and denominator.
An unsupported wrapper is rejected: p50(count()) fails with a message naming the six that work. So does merge() over an aggregate that has no cross-trace strategy, such as merge(top3(_name)).
Rate functions are the only non-aggregate wrappers allowed, and they keep the grain of what they wrap: perMin(count($db)) rates a representative trace's count, while perMin(merge(count($db))) rates the cell total. Any other scalar wrapper is rejected (lower(min(...)), toStartOfHour(min(...))), and two rate functions cannot be nested.
Supported Aggregates
A cross-join reference must appear inside an aggregate — min($db._dur_ms), not a bare $db._dur_ms — because a trace can contain many matching child spans that must be reduced to a single value. The exception is count($db), countAll($db), and countDistinct($db), which take the alias with no attribute: they count the child's spans, so there is nothing to reduce.
| Aggregate | Example | Description |
|---|---|---|
min, max | max($db._dur_ms) | Smallest / largest child value |
sum | sum($db._dur_ms) | Total of a child value within one trace |
count, countAll, countDistinct | count($db) | The child's span count. The only forms that take a bare $alias with no attribute; each equals the child row's own count(). |
countIf | countIf($db._status_code = "error") | Child spans matching a predicate, evaluated against the child spans |
avg | avg($db._dur_ms) | Average child value |
median, p50, p75, p90, p95, p99 | p99($db._dur_ms) | Child value percentiles |
quantile | quantile(0.95, $db._dur_ms) | Arbitrary child quantile |
uniq | uniq($rpc.service_name) | Number of distinct child values |
any, anyLast | any($db.db_statement) | A representative child value |
Every one of these is a per-trace value on its own; wrap it to merge across the cell.
Conditional *If combinators work too, with the predicate evaluated against the child spans:
root: count() | merge(countIf($db._status_code = "error")) as failed_queries | group by _group_id
db:all as db:
top3 / top10 and apdex cannot be projected per trace at all, and are rejected in any form.
Per-Trace Expressions
A child aggregate and a root aggregate can be combined in one expression — most usefully a trace's own duration, the gap between its root start and its latest child span:
root: max($child._time) - min(_time) | group by _group_id
spans:all as child:
Such a mixed expression is evaluated per trace: for each trace, max($child._time) is that trace's latest child time and min(_time) its own root start. An outer aggregate then merges those per-trace values across the cell:
- bare, or wrapped in
any(...)/anyLast(...)— one representative trace's value. max(...)/min(...)— the longest / shortest such value in the cell.max(max($child._time) - min(_time))is the slowest trace's duration.sum(...)/avg(...)— the total / average across the cell's traces, each trace counted once.sum(count($child) + count())totals the child and root spans of every trace in the group.
Those six are the valid outers. count / countAll, the percentile and state family (p50–p99, median, quantile, uniq, countDistinct), and top3 / apdex are rejected as outers over a per-trace value.
The expression is rendered inline in the main query, with no extra subquery: the root-to-child join already carries one row per trace, so the outer aggregate counts each trace once. That is what makes sum and avg exact here — under the same one-root-per-trace assumption the rest of the feature makes.
Three things are rejected inside such an expression:
- A member that is not a bare aggregate. Every child aggregate in the arithmetic must be bare, because only the bare form carries a per-trace value. A merge wrapper (
sum(count($child))), amerge(...), or a rate function (perMin(...)) asks for a cell-level value that no per-trace row holds. Which aggregate it is does not matter —p90($child._dur_ms) - min(_time)is fine. - A second join alias. Two join subqueries share no per-trace row to combine.
- A predicated or non-scalar root aggregate.
minIf(_time, _kind = "server")has no single-row value, and neither doesapdex(),quantiles(...), ortop3(...).
The remaining root aggregates collapse to their single-row value: count() and countAll() become the root row's weight, uniq() and countDistinct() become 1, and a value aggregate such as min(x) or p95(x) becomes x.
Child Columns as Output
Beyond plain selectors, a group by in a child row is also exposed to the root — it becomes an extra output dimension, so the result splits into one row per (root group × child group):
root: count() | group by _group_id
db:all as db: merge(sum(_dur_ms)) as db_time | group by service_name
The result has a row per (_group_id, $db.service_name) with a $db.db_time column — the database time of that service for each root group, totalled across the cell's traces.
Filtering per Trace with having
A bare reference is a per-trace value, so in a having clause the useful reading is a per-trace filter, not a comparison against one arbitrary representative. A conjunct written purely over one alias's bare references is therefore pushed down into that child's subquery, where it filters trace by trace: only traces that individually satisfy it survive the join.
root: count() | having count($db) > 10 | group by _group_id
db:all as db:
This compiles to the same query as putting the condition in the child row:
root: count() | group by _group_id
db:all as db: having count() > 10
Top-level and conjuncts are split, so a pushable one travels while its siblings stay. A rate function over such a reference (having perMin(count($db)) > 5) is pushed too. These are not pushed, and are compared against the merged cell value instead: a conjunct using a merge wrapper or merge(...), one that spans two aliases, one that mixes in a root aggregate, and anything under a top-level or.
Restrictions
A single cross-join aggregate is pushed down into one child subquery, which constrains what it may contain:
| Not allowed | Example | Why |
|---|---|---|
| Two aliases in one aggregate | minIf($db._time, $rpc._name = "x") | An aggregate can reference only one join alias. |
| A root attribute inside the aggregate | minIf($db._time, service_name = "x") | Move the root condition to a separate where. |
| A second level of nesting | max(sum(min($db._time))) | One wrapper is a merge; a second cannot run in the subquery. |
| A type-mismatched argument | sum($db._name) | sum needs a number; _name is a string. |
| A non-mergeable aggregate | top3($db._name), apdex($db._dur_ms) | Neither has a per-trace partial to merge. |
| A non-rate scalar wrapper | lower(min($db._name)) | Only perMin, perSec, and rate may wrap a reference. |
Examples
Traces with Many Child Spans
Find traces that contain more than 1000 child spans, which can indicate runaway loops or excessive instrumentation:
root: perMin(count()) | quantiles(_dur_ms) | _error_rate | group by _group_id
spans:all as db: count() | having count() > 1000
Traces with the Number of Database Queries
Return each group along with how many database queries its traces contain in total. A bare count() is one trace's count, so wrap it to total across the cell:
root: perMin(count()) | quantiles(_dur_ms) | _error_rate | group by _group_id
db:all as db: merge(count()) as db_queries
sum(count()) gives the same total. Drop the wrapper for a representative trace's count, or use max(count()) for the busiest trace.
To compute the total inline in the root — without adding a child selector — reference the alias with no attribute: merge(count($db)).
Traces with Multiple Database Queries
Find traces that contain at least 2 PostgreSQL queries:
root: perMin(count()) | quantiles(_dur_ms) | _error_rate | group by _group_id
db:postgresql as pg: having count() >= 2
This is useful for identifying N+1 query problems or traces with excessive database calls.
Traces with Slow Service Calls
Find traces where a specific service takes longer than 1 second to respond:
root: perMin(count()) | quantiles(_dur_ms) | _error_rate | group by _group_id
rpc:all as rpc: where service_name = "foo" | where _kind = "server" | where _dur_ms >= 1000
Traces with Error Logs
Find traces that contain error logs mentioning "timeout":
root: perMin(count()) | quantiles(_dur_ms) | _error_rate | group by _group_id
log:error as err: _display_name contains "timeout"
Traces with Errors in a Specific Service
Find traces where a particular service returned an error:
root: perMin(count()) | quantiles(_dur_ms) | _error_rate | group by _group_id
rpc:all as rpc: where service_name = "payment-service" | where _status_code = "error"
Traces with Slow Root Spans
Find traces where the root span exceeds 5 seconds:
root: where _dur_ms >= 5000
Combining Multiple Conditions
Find traces that are slow and contain database errors:
root: where _dur_ms >= 3000
db:all as db: where _status_code = "error"
This selects traces where the overall duration exceeds 3 seconds and at least one database span has an error status.
Slowest Database Query per Group
Add the slowest database query across each group's traces. A bare max(_dur_ms) is the slowest query in one trace, so merge it across the cell:
root: count() | group by _group_id
db:all as db: merge(max(_dur_ms)) as slowest_query_ms
max(max(_dur_ms)) is equivalent here — for an idempotent aggregate the natural merge and the plain one coincide.
Total Database Time per Group
Sum the database time of every query across a group's traces, next to the root duration. A bare sum(_dur_ms) is one trace's database time, so merge it across the cell:
root: count() | p50(_dur_ms) as p50_total_ms | group by _group_id
db:all as db: merge(sum(_dur_ms)) as db_time_ms
A large $db.db_time_ms relative to p50_total_ms points at database-bound groups. For the mean database time of a trace rather than the total, use avg(sum(_dur_ms)).
Distinct Downstream Services per Group
Count the distinct downstream services each group fans out to across its traces. Only merge deduplicates a distinct count across traces — a plain merge would count a service once per trace it appears in:
root: count() | merge(uniq($rpc.service_name)) as downstream_services | group by _group_id
rpc:all as rpc:
The child form rpc:all as rpc: merge(uniq(service_name)) is equivalent.
Error Logs per Group
Total the error logs across a group's traces:
root: count() | _error_rate | group by _group_id
log:error as err: merge(count()) as error_logs
Use max(count()) instead to find the single trace that logged the most errors.
N+1 Query Detection
Filter to traces that issue many queries — the child having is evaluated per trace — and report the worst trace's query count with the max(count()) wrapper:
root: count() | group by _group_id
db:all as db: max(count()) as max_queries | having count() >= 10
The having keeps only traces with at least 10 database spans; $db.max_queries is the largest per-trace query count among the qualifying traces in each group. Writing the filter in the root as having count($db) >= 10 compiles to the same query — see Filtering per trace.
Slowest Trace Duration per Group
Combine a child aggregate with a root one to get each trace's duration — its latest child span minus its root start — then take the slowest in each group with the max(...) outer:
root: count() | max(max($child._time) - min(_time)) as slowest_trace_ms | group by _group_id
spans:all as child:
The inner max($child._time) - min(_time) is evaluated per trace; max(...) merges those durations across the cell. Use any(...) instead for a representative trace rather than the slowest. See Per-trace expressions.
Total Spans per Group
Count every span a group's traces emit — root spans plus all their children — by adding the child row count to the root count per trace, then summing across the group:
root: sum(count($child) + count()) | group by _group_id
spans:all as child:
count($child) is the child span count of one trace and count() its root span count, so count($child) + count() is that trace's total. The sum(...) outer adds those per-trace totals across the group. A large value relative to the trace count signals broad fan-out or chatty instrumentation. This is a per-trace expression — sum and avg are exact here because the join carries one row per trace.
Database Query Rate per Group
Report how many database queries per minute each group runs across its traces. A rate function is transparent to grain, so it rates whatever it wraps — wrap the merged total, not the bare count:
root: perMin(count()) | group by _group_id
db:all as db: perMin(merge(count())) as queries_per_min
perMin(count()) would rate a single representative trace's count instead. perSec and rate behave the same way.
Pooled Child Percentile per Group
Report the p90 of every database query in a group, pooled across all its traces. This is the merge that has no other spelling: p90(_dur_ms) is one trace's p90, and avg(p90(_dur_ms)) is the mean of per-trace p90s, which is a different number:
root: count() | group by _group_id
db:all as db: merge(p90(_dur_ms)) as db_p90_ms
merge re-aggregates the underlying percentile state rather than the finished values, so the result is the true p90 over the group's database spans.
Available Clauses
Each row — both root and child — supports the full span query language including filters, aggregations, and groupings:
| Clause | Example | Description |
|---|---|---|
where | where service_name = "foo" | Filter spans by attribute values |
where | where _dur_ms >= 1000 | Filter by span duration |
where | where _status_code = "error" | Filter by status code |
where | where _kind = "server" | Filter by span kind |
where | where _display_name contains "text" | Filter by display name |
group by | group by _group_id | Group spans by attribute |
group by | group by service_name | Group by service |
| Aggregates | count(), perMin(count()) | Count and rate aggregations |
| Aggregates | p50(_dur_ms), quantiles(_dur_ms) | Duration percentiles |
having | having count() >= 2 | Filter by aggregated span count |
having | having p99(_dur_ms) >= 500 | Filter by percentile duration |
merge | merge(p90(_dur_ms)) | Re-aggregate a child value across the group's traces |
The root row additionally supports cross-join expressions (min($alias._dur_ms)) that aggregate a child row's spans within the same trace. A having conjunct written over one alias's bare references is pushed into that child and filters trace by trace.
Multiple clauses can be chained with the pipe | operator:
rpc:all as rpc: where service_name = "foo" | where _kind = "server" | where _dur_ms >= 1000
See Also
- Querying spans and logs - Query language fundamentals
- Span query language reference - Every field, function, and operator
- Searching spans and logs - Simpler search syntax
- Grouping and systems - How span systems work